Home Blog Page 41

Modern Digital Security Practices Using Octo Browser

0
Modern Digital Security Practices Using Octo Browser

In this post, I will discuss the modern digital security practices using Octo Browser.

Online security is no longer just about strong passwords and antivirus software. Today, websites and apps “recognize” you using many subtle signals—device behavior, browser characteristics, network patterns, and even timing patterns. If you understand how these signals work, you can protect accounts more effectively and reduce the risk of account takeovers, fraud flags, and unwanted tracking.

In this article, we’ll explain digital fingerprinting in simple terms, why it matters for privacy and security, and what modern security-minded teams do to manage risk responsibly. We’ll also cover how Octo Browser approaches secure, organized browsing for multi-account environments—so you can learn practical concepts even if you’re not technical.

Note: This article is educational. It focuses on general security, privacy, and account safety concepts, and on how fingerprint management can be used to reduce tracking and reduce operational risk.

1) What “Digital Fingerprinting” Really Means (In Plain English)

A digital fingerprint is a bundle of information that helps a website figure out “what kind of device” you’re using and “whether you might be the same person” across sessions.

Even if you don’t log in, many websites can still observe your device/browser/network traits. When you do log in, the website often combines device traits with account data to build a higher-confidence profile of the user.

Common fingerprint signals (examples)

A fingerprint can be built from things like:

  • Browser and settings traits (browser type, version, installed components)
  • Screen and display characteristics (resolution, pixel density)
  • Timezone and language preferences
  • Headers and network behavior
  • Cookies and local storage behavior
  • Interaction patterns (sometimes timing-related)

No single signal usually “identifies you” perfectly. Instead, it’s the combination that becomes meaningful.

Why fingerprints are important for security

Fingerprinting matters because it affects:

  • Account security: suspicious devices can trigger extra verification steps—or, in worse cases, enable attackers to blend in.
  • Fraud detection: platforms use fingerprint signals to detect bot-like behavior.
  • Privacy: the same traits can let trackers recognize you across websites.

Modern security practice isn’t about “hiding everything.” It’s about reducing avoidable exposure, improving account isolation, and using risk controls that match your real situation.

2) Where Fingerprinting Meets Real-World Risk

Think about typical scenarios people face:

  1. You log in from a new device
    Many platforms require extra checks because device identity seems “different.”
  2. You switch networks often (home → mobile → office)
    Some websites may treat it as abnormal and throttle or ask for verification.
  3. Your organization manages many users or accounts
    Without careful separation, one user’s settings can affect another. That can create both security and operational problems.
  4. You run legitimate automation or data collection
    Even if you’re not doing anything wrong, behavior that looks unusual can still trigger anti-fraud defenses.

So, in security terms, fingerprinting is part of a broader system:

  • Detection (anti-fraud systems measuring suspiciousness)
  • Risk scoring (assigning a likelihood of fraud)
  • Controls (CAPTCHAs, rate limits, bans, additional verification)

Your goal is to reduce unnecessary “risk signals” caused by careless device handling—without undermining legitimate protections.

3) How Fingerprints Are “Used” by Websites (High-Level)

At a high level, platforms do something like this:

  1. Observe device/browser/network characteristics.
  2. Compare them to prior behavior for that account (if any).
  3. Look for inconsistencies or suspicious patterns.
  4. Decide what security response to apply.

This doesn’t mean the platform is “wrong” to do this. It means:

  • they are trying to protect users,
  • and you should build workflows that behave consistently and responsibly.

A key takeaway: inconsistent browser/device handling across sessions increases uncertainty. Uncertainty often increases friction (verification) or blocks.

4) Introducing Octo Browser (Anchor Text in the First Half)

In the modern multi-account and privacy world, managing fingerprint consistency and account separation becomes a practical security task—not just a convenience feature. That’s where Octo Browser comes in.

Octo Browser is positioned as an antidetect browser solution for multi-accounting and privacy-focused browsing, helping users create and manage multiple accounts from a single device. According to the Octo Browser site, it supports multi-accounting tasks across many platforms and emphasizes profile handling using “digital fingerprint of a real device,” along with organized profile management, proxies, and team controls.

From a security mindset, the important parts to understand are not only the “anti-detect” label, but the operational security building blocks implied by their approach:

  • Profile separation (reduce account cross-contamination)
  • Consistent fingerprinting per profile (reduce “identity drift”)
  • Proxy control (manage network identity more deliberately)
  • Team access controls (reduce internal operational risk)

If you’re responsible for safe account operations—especially at scale—these controls can matter as much as classic cybersecurity measures like 2FA and password hygiene.

5) Why Multi-Account Environments Need “Security-First” Isolation

Many people think security only applies to passwords and 2FA. But in real operations, isolation matters.

What isolation means (simple definition)

Isolation means:

  • keeping each account’s browsing context separated,
  • so one account’s behavior doesn’t accidentally “leak” into another account’s session patterns.

When isolation is weak, you can get:

  • inconsistent login history,
  • suspicious session combinations,
  • higher chance of forced re-verification,
  • harder troubleshooting.

Octo Browser emphasizes multi-account workflow support, along with profile management features like tags/templates and bulk actions, plus high-quality fingerprint focus. 

Even if you don’t need multi-accounting, the underlying concept is general:

Security is easier when you reduce accidental mixing of identities and contexts.

6) Fingerprint Management as a Responsible Security Practice

Let’s be careful: people use the term “fingerprint management” for different purposes. But from a defensive standpoint, fingerprint management often means:

  • reducing unwanted tracking,
  • minimizing unpredictable identity changes,
  • keeping profiles consistent so security systems don’t see you as “anomaly-like,”
  • protecting operational stability.

Consistency reduces friction

If your browser environment changes unpredictably (settings, device attributes, network signals), some platforms may interpret that as risk.

So a responsible approach is:

  • build stable, repeatable browser context per purpose,
  • avoid “random” configuration changes mid-workflow,
  • ensure each account stays within its intended environment.

This is where fingerprint-handling tools are marketed as helpful: they aim to provide stable identity signals per profile.

7) Proxies: Useful, but Also a Security Consideration

Proxies often get discussed as a way to “change IP.” But from a security and risk perspective, proxies are more than that:

  • They can affect geolocation signals,
  • they can affect latency patterns and connection behavior,
  • they can influence reputation.

Octo Browser advertises a “Built-in Proxy Shop,” with residential proxies chosen directly in the browser.
It also emphasizes tested providers to reduce bans caused by “faulty expendables.” 

Even without endorsing any specific use case, you can take the security lesson:

Network identity is part of your security posture. Manage it intentionally instead of leaving it chaotic.

Security teams typically prefer:

  • predictable network behavior,
  • consistent egress routing,
  • controlled access to network paths.

8) Teamwork and Access Control Reduce Internal Risk

For organizations, one of the biggest security threats is often internal mishandling:

  • shared credentials,
  • unclear permissions,
  • lack of accountability,
  • uncontrolled profile usage.

Octo Browser describes “Advanced and Flexible Team Management,” including permission configuration, password protection for profiles, tag access rights, and tracking via an action log. 

That matters because security is not only external. It’s also:

  • who has access,
  • what they can do,
  • how actions are logged,
  • how quickly you can respond to anomalies.

A responsible operational setup includes:

  • principle of least privilege,
  • clear separation of responsibilities,
  • auditability.

9) Data Protection and Account Safety Mindset

Modern digital security includes protecting both:

  1. Your accounts (login integrity, account recovery, 2FA)
  2. Your operational data (configuration, credentials, profile metadata)

The Octo Browser site claims “Reliable Data Protection,” describing a hack-resistant architecture, end-to-end encryption using profile passwords, and two-factor authentication protections.

Whether you use Octo Browser or not, you should apply the same principles:

  • protect sensitive configuration,
  • enable 2FA everywhere you can,
  • limit access to sensitive profile/workflow data,
  • keep recovery options secure.

Security isn’t only a technical setting—it’s also a process.

10) A Practical Security Checklist for “Fingerprint-Aware” Browsing

Here’s a simple checklist you can apply whether you manage one account or dozens. This makes the concept actionable.

A) Before you start

  • Use strong, unique passwords.
  • Enable 2FA.
  • Decide what each account/profile is “for” (purpose-based separation).
  • Keep environment configuration consistent per purpose.

B) During daily work

  • Avoid sudden environment changes (settings, device identity, abrupt network switching).
  • Monitor for unexpected verification prompts or throttling.
  • Keep a basic log of changes you made (for troubleshooting).

C) For teams

  • Use least-privilege access.
  • Separate responsibilities (who can create/edit vs who can just run).
  • Use permissioning and audit logs where possible.

D) After issues

  • If you get repeated blocks, don’t “spam retries.”
  • Investigate what changed: network, browser setup, usage pattern.
  • Reduce variables until you find the cause.

This checklist aligns with modern security practice: reduce uncertainty, keep consistent context, and maintain accountability.

11) Security vs. “Evasion”: How to Think About It Correctly

It’s easy to misuse fingerprint tools if you interpret them as a way to bypass safety systems. A more productive approach is to frame fingerprint consistency as:

  • privacy-friendly organization,
  • operational stability,
  • account isolation,
  • reducing accidental anomalies.

If a platform uses device traits to protect users, security-conscious behavior means:

  • respecting legitimate workflows,
  • reducing avoidable risk signals,
  • improving your own safety practices.

In other words:

Manage your digital identity responsibly, not recklessly.

12) Realistic Outcomes: What Better Fingerprint Handling Can Improve

Depending on your use case, improving consistency and isolation may lead to:

  • fewer unexpected login challenges,
  • easier debugging (because environment changes are controlled),
  • reduced operational chaos across multiple accounts,
  • better internal control for teams.

Octo Browser’s positioning emphasizes convenience and profile management, fingerprint focus, proxy handling, team management, and stability/uplift claims like uptime approaching 100%.
Even if you don’t rely on every claim, the general concept remains valid: tools that help you keep environments stable often improve operational reliability.

13) Common Questions People Ask (Quick Answers)

Q1: Is fingerprinting the same as tracking cookies?

No. Cookies are one component. Fingerprinting can also include browser settings, network behavior, and other device characteristics.

Q2: Why do I get challenged when I’m just logging in?

Platforms often treat device/network changes as risk indicators—especially if signals don’t match prior behavior for that account.

Q3: Does stronger fingerprinting always mean better security?

Not automatically. Security also depends on account-level protections (2FA), credential hygiene, and careful operational practices.

Q4: What’s the best approach for a non-technical person?

Keep it simple:

  • use 2FA,
  • avoid random environment changes,
  • keep accounts separated by purpose,
  • and use reputable tooling that supports consistent profile handling.

14) Conclusion: Build Digital Security on Consistency, Isolation, and Control

Modern digital security is about more than passwords. It’s about how your device identity behaves across time, sessions, and networks. Digital fingerprinting turns subtle browser and network signals into risk decisions, and those signals can impact account access and platform protections.

A security-first mindset focuses on:

  • consistent environments per purpose,
  • separation (isolation) of accounts/profiles,
  • controlled network behavior,
  • team permissions and auditability,
  • and strong account protection like 2FA.

Tools like Octo Browser are marketed to help users manage multi-account environments through profile handling, fingerprint-focused behavior, proxy control, team management, and data protection features. 


INTERESTING POSTS

Agentic SOC: How Agentic MXDR Is Reshaping Enterprise Cyber Defense

0
Agentic SOC: How Agentic MXDR Is Reshaping Enterprise Cyber Defense

In this post, I will give you the Agentic SOC guide and show you how Agentic MXDR is reshaping enterprise cyber defense.

Security teams are always pushed to be faster, go further and remain in control at all times. The pressure is driving the sector towards a new framework which is referred to as the Agentic SOC. The model leverages AI agents to do most of the repetitive tasks rather than using human analysts to complete the same. People will retain control when it comes to decision-making, unusual cases and actions with inherent risks involved.

The intention is quite clear. Cut down the number of hours wasted working manually. Enhance the consistency and quality of all the cases analyzed at the SOC. Transform the raw intelligence data to actions rather than having them stored. And most importantly, gain an improved visibility in terms of risks, workload and overall SOC performance.

This is where cybersecurity AI technology is really heading. AI has progressed beyond becoming a mere summarizing agent of text data. Rather, it has become a network of specialized, task-specific agents able to perform many tasks including enriching alerts, mapping activities to known TTPs of adversaries, hunting operations for finding unknown threats, generating notes for investigations and pre-approved responses actions.

What “Agentic SOC” Actually Means

Agentic SOC refers to the approach in which the artificial intelligence agents perform specific tasks within their own roles, boundaries, and checkpoint. For example, one agent may create a threat actor profile, another one – connect observed events with the MITRE ATT&CK framework, the third one – build a hunting query, and the fourth one – abstract an alert for the analyst to review.

It is much further than simple automation as traditional SOAR playbooks follow predefined logic while agents have the opportunity to use contextual information, think over it, and pass on to another agent within the chain of actions.

A properly designed Agentic SOC does not exclude people from process but gives new sense to their work. They do not waste time on transferring information between different systems but concentrate on the scope, business relevance, and response actions.

Why the Old SOC Model Is Breaking Down

The volume of alerts has now evolved into a leadership issue. Detection tools are becoming increasingly effective in identifying real risk signals; however, this presents an additional challenge to the SOC since it could lead to a deluge of real alerts being generated simultaneously. Alerts come from all over – endpoints, cloud workload, identities, emails, SaaS applications, and network sensors. Each one is potentially valuable to the SOC; however, it must determine the relative value of each alert in an efficient manner. This is where agentic methods step in since context would be provided instantly.

Manual case management is inefficient and problematic. Manual processing accounts for a considerable proportion of the SOC’s work – from log pulls, threat feed analysis, asset data collection, tactic mapping, summary generation, and notifications of status changes. All of this takes time and the quality of the results depends on the personnel on shift. AI agents would ensure efficiency of the process by gathering all the information and forming a timeline and an estimation of impact, leaving only approvals or changes in the hands of the analyst.

Fragmentation in tooling makes the bigger picture difficult to see. The fact of the matter is that large companies usually have great tools, but little integration between them. SIEMs, EDRs, XDRs, cloud platforms, identity solutions, ITSM, and threat intel feeds seldom have sufficient information about each other. This is where the agentic approach of MXDR comes into play. It provides the necessary path of going from raw signal to insight to action without leaving tools behind.

What an Agentic SOC Actually Does

Coordinated Agents Across the Security Lifecycle

The true value of an Agentic SOC is not in its triage bot, but in a system of interwoven agents. Common agents to run are:

  • Threat profiling agents that order relevant actors, campaigns, and attack vectors
  • Agents that validate MITRE coverage and detect any coverage gaps
  • Threat hunting agents that generate queries based on telemetry from SIEM, EDR, and cloud systems
  • Investigation agents that augment raw alerts and create timelines for cases
  • Summary agents that digest case details and generate a concise narrative
  • Agents that verify the state of sensors and detect policy drift in EDR systems
  • Agents that validate case completion according to company processes

Agents interact with each other in a cycle: threat intelligence leads to hunts, hunts result in new detections, improved detections lead to better alerting and case results become input for new tuning efforts.

Keeping Humans in Control of High-Risk Decisions

Agentic AI in cybersecurity is effective when there are genuine guardrails because we do not want unrestricted power for the agents. The good thing about a proper framework is that it sets out:

  • The list of agents authorized to operate independently
  • The list of actions that are subject to analyst approval
  • The type of users or hosts which will require caution
  • What documentation needs to be done
  • What changes need change control
  • What kind of mistakes would trigger a review

This matters most for sensitive actions like isolating an endpoint, altering account permissions, deploying blocking rules, or pushing new detection logic. Speed only has value when it doesn’t come at the cost of safety.

Prioritizing by Real Business Risk

Not every alert deserves equal attention. A mature SOC filters work through the lens of what actually matters to the organization:

Priority LensGuiding QuestionWhat It Delivers
Threat relevanceWhich actors are actively targeting our sector or region?Sharper focus
Asset contextWhich systems are most critical to the business?Better triage decisions
Exposure dataWhich assets sit on known, exploitable attack paths?Faster remediation
Detection gapsWhich tactics could slip past us right now?Stronger coverage
Response readinessWhich actions can we approve without delay?Faster containment

This is the shift from an alert-driven SOC to a risk-driven one.

How Agentic MXDR Extends Traditional MDR

Agentic MXDR leverages the principles of MDR, XDR, SOAR, threat intelligence, and hunting but incorporates AI agents alongside analysts within a single managed service. It does not involve a complete replacement of existing tools prior to creating value; instead, a powerful Agentic MXDR model leverages the existing capabilities and integrates immediately with SIEM, EDR, XDR, cloud, identity, email, and ITSM platforms.

An ideal implementation of this approach involves the convergence of three components:

  • AI agents responsible for speed, scalability, and repetitive work
  • Human analysts offering insights, accountability, and supervision
  • Co-managed service layer enabling reporting, review, and joint decision making

This is the formula that enables value delivery for CISOs, CIOs, and SOC managers – it reduces the burden of manual operations while allowing tracking of SOC activity, its motivations, and risk transformation.

A Reference Model for Agentic Security Operations

Data layer. The agents should have reliable access to the right information such as endpoint events, identity log files, cloud alerts, e-mail indicators, SaaS activities, network traffic, vulnerability details, asset information, and threat intelligence. It is not important for us to bring all the bytes of information together in a single storehouse; rather, our objective is to ensure availability of relevant information at the time of need.

Agent layer. Every agent needs a clearly scoped task, defined inputs, permitted outputs, and rules for when a human needs to step in:

Agent TypeInputOutput
Threat profilerCTI feeds and customer risk profileRanked list of actors and campaigns
MITRE mapperDetection rules and case evidenceTechnique mapping and coverage gaps
Hunt builderHypotheses and indicatorsSearch logic and queries
InvestigatorAlerts and telemetryCase timeline and recommended action
Case summarizerNotes and completed actionsReadable case summary
EDR health checkerEDR status and policy dataCoverage and drift report

The idea of the Agentic SOC gets put into practice rather than remaining purely theoretical at this point — the agents have to be actually helpful, rigorously evaluated, and well-integrated with current SOC procedures.

Service layer. The leaders require insight on the current situation. It would be wise to create a shared, co-managed system that could show the status of the cases, KPIs, pending actions, and services trends, along with the current level of risk.

Where to Start: High-Value, Low-Risk Use Cases

A good starting point for adopting an Agentic SOC would be tasks which are prevalent, easy to prove, and quantifiable in terms of results. Some of the possible examples may include:

  • Context enrichment of alerts
  • Case writeups for analysts’ approval
  • Mitre ATT&CK mapping verification
  • Threat hunting query generation
  • EDR checks and coverage
  • Detection gaps analysis
  • QA of SOC cases according to established procedures
  • Notes for the responses to approved actions

All these use cases save time without introducing any extra risk.

Metrics That Prove the Model Is Working

An Agentic SOC needs to be judged on measurable outcomes, not marketing claims. CISOs need proof that risk is actually going down. CIOs need to see better returns on their security investments. SOC managers need evidence of faster, more stable operations. Useful metrics include:

MetricWhat It Reveals
Mean time to acknowledgeHow quickly the SOC begins working an alert
Mean time to investigateHow fast facts get gathered
Mean time to respondHow quickly action becomes ready
Agent-assisted case rateHow often agents cut down manual effort
QA pass rateHow consistent case handling is
Detection gap closureHow quickly weak spots get addressed
Hunt-to-rule conversionHow often hunting leads to stronger detection
EDR health coverageHow prepared the environment is overall
Analyst time savedHow much effort shifts toward higher-value work

These numbers are what turn Agentic MXDR into a genuine business case rather than just another technology purchase.

Bringing It Together: Human Oversight Plus Agent-Driven Scale

In this respect, an effectively designed Agentic MXDR solution should focus on co-management of threat-informed operations based on the integration of MDR, XDR, threat intelligence, threat hunting, automation, and AI agents within a unified service model where human intervention is ensured at all stages of the process. The analysts verify results, take responsibility for complicated cases, conduct the responses, and optimize the process, while agents perform the burden of the repetitive tasks of collecting the context, triaging, investigation, summarizing, system status check, technique mapping, and hunt query building.

Moreover, such a model has to be adaptable to the ecosystems which enterprises use — platform-agnostic but able to evaluate other third-party or proprietary agents if there is a real lack of some capabilities. No enterprise wants to acquire one more separate solution; instead, what is needed is a solution tailored to their specific ecosystem and operational practices.

A Practical Roadmap for Getting There

Begin with simple and high-volume activities. Case summary creation, alert enrichment, EDR health check-ups, and MITRE mapping are all good ways to start out — they give immediate savings in time and demonstrate the validity of your approach.

Move into guided investigation and hunting. With that under their belts, the agents will be ready for triage, timeline building, hunt queries and gap analysis. These activities require wider access to data but provide greater value in return.

Close the feedback loop. In their mature form, the agents work together as a closed loop process: threat intel powers hunting, hunting generates new rules which improve alerts, case quality assurance improves the next iteration of the process, and finally reporting provides evidence of the gains in speed and effectiveness of the process. It’s at this stage when you have a real Agentic SOC.

If you’re looking for Agentic SOC services, we’re here to help. Our Agentic Security Operations Center (SOC) combines AI-driven automation with expert security monitoring to detect, investigate, and respond to cyber threats in real time. Cyberproof provides 24/7 threat detection, rapid incident response, proactive threat hunting, and continuous security monitoring to help protect your business from evolving cyber risks while improving operational efficiency.

The Bottom Line

Agentic SOC is not about complete autonomy; it is a real and actionable approach to defense, which is quicker, safer, and more consistent. Agents take care of the repetitive part of the work. Humans stay in charge of the subjective decisions. Management sees clearly how the value is created. And thus, we receive a SOC that changes from being reactive and alert-oriented to a risk-based approach.

For CISOs, this would mean a greater concentration on the risks. For CIOs – maximizing the value of security investments. For a SOC Manager – quality outcomes without extra burden for the team.

The area of using AI in cyber will continue its rapid development. The wrong way to do things here is not about blindly trusting the self-directed agent – it is an agentic security operation approach with proper scope, guardrails, common metrics and regular human checks.


INTERESTING POSTS

Track Smart Money, Copy Top Traders, Execute in Seconds: Inside Banana Predict

0
Track Smart Money, Copy Top Traders, Execute in Seconds Inside Banana Predict

In this post, I will talk about Banana Predict.

Most people trading prediction markets are guessing. They open a market, read a headline, and click Yes or No on a hunch.

Banana Predict is built for a different kind of trader. One who wants to see who is actually winning before putting money down, then move fast enough to matter.

The platform’s own pitch sums it up in three parts: track smart money, copy top traders, and execute in seconds. Here is what each piece looks like when you actually use it.

Track Smart Money Before You Trade It

Every event market has a crowd reacting to news. The trick is knowing which part of that crowd is worth watching.

The Social Tracker (also called the X Tracker) watches X in real time. Search by contract address, token symbol, or username, then filter with All, Recommended, or Mine tabs.

Posts, retweets, and quotes land in your feed within seconds of going live. Turn on audio alerts and you catch a breaking story the moment it hits, not five minutes later when it is already priced into the market.

Pair that with the Wallet Tracker. Instead of following accounts, you follow wallets. Pick an address with a track record and watch what it trades, when it enters, and when it exits.

Between the two tools you get the narrative side and the money side of the same event. News breaks on X. Capital moves on-chain. Banana Predict lets you watch both at once instead of piecing it together across five browser tabs.

Copy Top Traders Instead of Starting From Zero

Not everyone wants to build a wallet-watching routine from scratch. That is what the Leaderboard is for.

It ranks top traders by profit and loss and by volume, and every wallet on it is public. You can open any trader’s history and see exactly how they got there, market by market.

Once you find someone whose approach fits your own risk appetite, Copytrade lets you mirror their positions directly. No need to research every market they enter or second-guess the timing.

This is the part of the pitch that removes the steepest learning curve. You do not need a trading course or months of paper trading to get a feel for prediction markets.

You need a leaderboard, a few traders worth following, and the willingness to copy what already works.

Execute in Seconds When the Market Moves

Spotting an edge means nothing if execution lags behind it. This is where Banana Gun’s speed carries over into event trading.

Every market on Banana Predict runs on a live order book showing price, share depth, and value at each level, alongside cent-priced shares and a running probability percentage.

Price charts across 1H, 6H, 1D, 1W, 1M, and All timeframes show you exactly how sentiment shifted before you got there.

When you are ready, Yes/No trading executes fast, with a payout preview so you know your exact return before you confirm. A Rules section on every market spells out resolution terms up front, so there is no ambiguity about how or when a market settles.

Liquidity is deep enough to matter too. Markets mirror Polymarket-scale volume, with the largest events carrying billions in liquidity and resolution following a UMA-style oracle process.

One Workflow, Three Tools

Put the pieces together and the workflow looks like this. Social Tracker flags a story breaking on X. Wallet Tracker shows you whether smart money is already positioning around it.

You check the Leaderboard to see who has a proven edge in that category, then use Copytrade if you would rather ride their position than build your own from scratch.

Either way, the order book and fast Yes/No execution mean you act on the signal while it still matters, across sports, politics, crypto, and breaking news.

That is the whole promise: trade Polymarket with Banana speed, without doing all the research alone.

Banana Predict is live now. Open the terminal, follow a wallet or two, and place your first trade before the market moves without you.


INTERESTING POSTS

7 Tools to Track Instagram New Follows (2026 Hands-On Review)

0
7 Tools to Track Instagram New Follows (2026 Hands-On Review)

In this post, I will disclose the 7 tools to track Instagram new follows.

Instagram no longer shows recent follows or followers in chronological order on profiles, creating frustration for users who want to monitor public account activity.

We tested 7 tools over several weeks to see which ones effectively track new follows and followers on public Instagram accounts. DolphinRadar stood out as the top performer for its anonymous, login-free access and detailed recent activity insights.

Methodology

We conducted hands-on testing over multiple weeks, evaluating public Instagram accounts across desktop and mobile browsers. Testing focused on public data only, with no login credentials provided to any tool. We assessed accuracy of recent follow/follower detection, ease of use, reporting features, and overall reliability based on real usage scenarios. All tools were reviewed for their ability to handle public profiles without violating platform policies.

DolphinRadar (#1)

DolphinRadar (dolphinradar.com) is a browser-based Instagram public-data analytics tool. It has no other domains.

DolphinRadar’s Recent Follow Tracker lets users see who any public Instagram account recently followed or was followed by. No Instagram login required. Results are anonymous.

Key features include:

  • Unlimited searches: track any number of public accounts with one subscription (unlike per-account tools).
  • Recent Follows and Recent Followers tabs with chronological sorting, something Instagram removed from its native interface.
  • Mutual follow detection with “Mutual” labels on each entry.
  • Gender breakdown statistics (Girls / Boys / Other).
  • Integration with Recent Mutual tracking: see which new follows are mutual (two-way), with email alerts for new mutual connections.

For deeper analytics, Social Insights (separate subscription, from $2.75/month annual) adds activity analytics, Ties and Trails social relationship mapping, and AI insights like MBTI and psychological analysis.

Pricing: $6/month (monthly), $4.99/month (quarterly, marked “Popular”), $4.16/month (annual, save 30%). Unlimited searches included in all plans.

Limitations: Only works with public Instagram accounts. New tracking takes approximately one week before the first report is available. Follow lists are based on the most recent data available and may not reflect real-time changes. DolphinRadar is available exclusively at dolphinradar.com. Any other domain using a similar name is not affiliated with the product.

Best for: Users seeking comprehensive, anonymous tracking of recent follows on any public Instagram account without login requirements.

  1. Snoopreport

Snoopreport is an Instagram activity tracker focused on public profile likes, follows, and interests.

  • Tracks new follows/unfollows with chronological lists.
  • Provides insights into liked posts and hashtag interests.
  • Generates reports on user activity.

Pricing: Starts around $0.99/week or monthly plans from about $4.99.

Limitations: Reports can sometimes be partial or delayed; limited effectiveness on certain accounts.

Unlike DolphinRadar, Snoopreport does not offer MBTI typing, Ties & Trails social-relationship mapping, or encounter-location analysis. DolphinRadar shows recent follows with visual timelines and mutual detection at a competitive price with unlimited searches.

Best for: Basic activity monitoring focused on likes and interests.

  1. FollowMeter

FollowMeter is a mobile app for Instagram account insights, primarily for your own profile.

  • Shows followers, unfollowers, and mutuals for your account.
  • Provides basic analytics like ghost followers.

Pricing: In-app subscriptions around $4.99/month or yearly options.

Limitations: Requires Instagram login and only analyzes your own account; aggressive ads in free version.

Where DolphinRadar tracks any public account anonymously without login, FollowMeter is limited to self-analysis and requires credentials.

Best for: Managing your personal Instagram account.

  1. Social Blade

Social Blade tracks social media statistics and growth trends across platforms including Instagram.

  • Monitors follower count changes over time.
  • Provides estimated earnings and ranking data.

Pricing: Free basic access; premium subscriptions from around $5/month for ad-free and advanced data.

Limitations: Shows aggregate trends but does not reveal specific individual follow actions.

Social Blade shows overall follower count trends but does not reveal who specifically followed or unfollowed, unlike DolphinRadar’s individual account-level follow tracking.

Best for: High-level growth statistics.

  1. HypeAuditor

HypeAuditor is an influencer marketing platform with audience analytics.

  • Fraud detection and audience quality scores.
  • Demographics and engagement insights.

Pricing: Starts around $299/month for basic plans (annual billing).

Limitations: Enterprise-focused pricing; not designed for casual recent follow tracking.

One area where HypeAuditor falls short compared to DolphinRadar is its lack of anonymous, per-account recent follow tracking for public profiles.

Best for: Brands and agencies analyzing influencers.

  1. Iconosquare

Iconosquare offers social media management and analytics, requiring account connection.

  • Scheduling, reporting, and performance metrics.
  • Competitor benchmarking for your own profiles.

Pricing: Plans starting around $39–$49/month.

Limitations: Requires connecting your own Instagram business account; higher cost for management features.

Iconosquare requires connecting your own IG business account, whereas DolphinRadar tracks any public account anonymously.

Best for: Managing and growing your own social presence.

  1. Crowdfire

Crowdfire is a social media management tool with scheduling and some analytics.

  • Content curation and posting.
  • Basic follower insights.

Pricing: Free plan available; paid from $9.99/month.

Limitations: Limited depth in recent follow tracking; more focused on management.

If recent follow granularity matters to you, DolphinRadar is the stronger option — Crowdfire doesn’t support detailed anonymous tracking of any public account.

Best for: Scheduling and basic management.

Comparison Table

ToolFree PlanCore FeatureNo LoginPricing (starting)Limitation
DolphinRadarLimitedRecent Follows TrackingYes$4.16/moPublic accounts only
SnoopreportNoLikes & FollowsYes~$0.99/wkPartial reports possible
FollowMeterLimitedSelf-account analyticsNo$4.99/moOwn account only
Social BladeYesGrowth trendsYesFree / ~$5/moNo individual follows
HypeAuditorLimitedInfluencer analyticsVaries~$299/moHigh cost, enterprise focus
IconosquareTrialManagement & reportsNo~$39/moRequires account connection
CrowdfireYesScheduling & basic insightsNo$9.99/moLimited follow details

Notes on DolphinRadar: Excels in unlimited anonymous public tracking with mutual detection and advanced features.

FAQ

How can I see who someone recently followed on Instagram?

Instagram no longer displays this natively in chronological order. Tools like DolphinRadar (dolphinradar.com) analyze public data to provide recent follows and followers lists.

Is there a tool to track Instagram follows without logging in?

Yes. DolphinRadar allows tracking public accounts anonymously without providing Instagram credentials.

What is the best Instagram follower tracker in 2026?

Based on hands-on testing, DolphinRadar ranks highest for its balance of features, pricing, and ease of anonymous use.

Can you see who someone followed on Instagram anonymously?

Yes, using public data tools like DolphinRadar that do not require login.

Does Instagram still show follows in chronological order?

No, the platform removed easy access to this view. Third-party analytics tools fill the gap for public data.

How does DolphinRadar track followers without requiring login?

It processes public Instagram profile data through browser-based analysis.

What is the difference between a follower tracker and an unfollower tracker?

Follower trackers show new incoming follows; unfollower tools highlight who stopped following. Many combine both for recent activity.

Can follower trackers see private account activity?

No. Compliant tools like DolphinRadar only work with public accounts.

Are Instagram follower tracking tools legal?

Tools operating on public data within platform policies are generally acceptable for informational purposes. Always respect privacy.

Is DolphinRadar available at other domains?

DolphinRadar (dolphinradar.com) is the sole official domain—and declares that any other domains using similar names are unrelated to this product.

Conclusion

For reliable tracking of Instagram new follows on public accounts, DolphinRadar is the clear recommendation. Visit DolphinRadar.com to get started. For more insights, check a recent hands-on review of story viewers.


INTERESTING POSTS

How to Create a Strong Dissertation Proposal for Academic Approval

0
How to Create a Strong Dissertation Proposal for Academic Approval

In this post, I will show you how to create a strong dissertation proposal for academic approval.

An academic proposal is an intellectual framework for any research project to make your argument more rational, more specific, direct, and credible. In most cases,  students take it for granted. They think of it as a middle-stage process that can be completed later on. But it is essential to complete it as quickly as possible. The structural argumentation issues are often restricted to the supervisor’s feedback and authorisation. The more quickly the process begins, the more coherent it becomes to avoid unnecessary revisions..

Core Ideas at a Glance:

  • A weak research question is the most frequent cause of proposal rejection at any level of education.
  • Feasible proposals, not necessarily original, are eligible for approval by supervisors.
  • Your literature review should not summarise existing literature; rather, it must determine a true gap.
  • Methodology justification is the major concern for master’s and students.

What is the Major Gap Nobody Talks About

Online resources on dissertation proposals mainly fall into two categories: those that provide a list of standard elements such as introduction, literature review, and methodology, and those that offer dissertation writing services. Some other reliable online resources include institutional digital toolkits, edtech platforms, academic blogs, open-access academic repositories, and commercial services. Scribber explains every aspect of dissertation writing and the available online resources.

We have covered in this guide how to identify common pitfalls in proposals. We also illustrate them with examples, including a poorly phrased research question, an unjustified methodology, and a lack of a credible literature review. Now, take a look at them one by one:

1. Development of the Research Question First

The research question is not a title;it is actually the answer of your entire dissertation.. The lack of clarity, and narrow domain-specificity, and meaningless argumentation are the most frequently cited reasons for the rejection of the proposals.

The topics which lack clarity, originality, feasibility, and clear objectives and defined research gap can not be approved. Before beginning to write any part of your proposal, test your research question with the three questions below: Can it be answered with the data that you can reasonably access? Is it a contribution to an area that is not sufficiently covered in previous literature? Does it fit in your word count and time frame?

Weak research question: “How does social media affect mental health?”

Stronger, refined research question: “To what extent does daily Instagram use among female university students aged 18–22 in the UK contribute to symptoms of anxiety, as measured by the GAD-7 scale, over six months?”

If you do not  know the answer to any of these, make an even more specific question. Supervisors are not going to turn down ambitious topics; they turn down topics that they cannot do anything.

2. Use Your Literature Review to Prove the Gap

A proposal literature review is not a summary of your resources. It is a selective synthesis that demonstrates your research requirements. Effective reviews involve examining and contrasting previous studies from different theoretical perspectives, methods, and results, and explicitly linking them to your proposed study.

Research gaps are defined into these three categories: theoretical gaps (incorporating limited conceptual frameworks), methodological gaps (dependence on certain methods or data sources), and empirical gaps (underexplored contexts, populations, or variables). To identify them, try critically reviewing recent peer-reviewed literature (preferably from the last 5-7 years). It clearly explains the gap and a lack of research in this context. On the other hand,for MBA proposals, the idea is to highlight the relevance of how this gap addresses a current question in industry/management? 

3. Justify the Methodology: Do Not Just Name It

Research Design

Just stating methods is not enough. Explain your decisions by connecting to your research question. For instance, why would a qualitative study, such as a semi-structured interview, be a better option than quantitative methods if the researcher intends to capture the complexities of experiences or processes?

Sampling and Data Collection

Explain why you chose this sampling strategy (purposive/snowball sampling, etc.) and data collection methods, and how they enable you to produce the data you need for the project in the timeframe you have available.

Ethical Considerations

Deal with ethical issues in a substantial manner, rather than simply checking off., The informed consent and confidentiality, are the potential risks to participants, and mitigation strategies.

At the master’s and doctoral levels, this section should demonstrate critical engagement with the methodology literature and a coherent, defensible research plan.

4. Involve Your Supervisor Before You Submit

Effective proposals do not  happen by chance. Communicate with your supervisor as early as possible about your research question, the proposed gap, and the preliminary methodology is the key to success. 

Prepare for meetings by sending a brief outline of what you have  covered in 1-2 pages. Ask for targeted input on feasibility, originality, and challenges. Read and listen carefully to feedback, ask for clarification, and follow up with a “new” draft that demonstrates what you took on board. This is the best method to save your time and the final approval of the proposal by early detection of weaknesses.

The Proposal Checklist Used by the Supervisors

ElementWhat Approval Requires
Research questionSpecific, feasible, and gap-driven
Literature reviewSynthesised argument that exposes a clear gap
MethodologyJustified, not just named, linked to the question
FeasibilityTimeline, data access, and scope are realistic
EthicsSpecific plan, not a generic statement with consent
ReferencesAccurately formatted in the required citation style


Conclusion

A first-attempt success proposal is not necessarily as long or as impressive as a proposal that does not get back to its first draft, but rather is better argued. All sections must relate to the research question, and each methodological decision must be explained rather than taken for granted.

Dissertation proposal help at the proposal stage is not only less expensive for you, but if you are unsure whether your proposal will hold together into a coherent argument, it is much better to have it done than to face rejection and have to redo your methodology chapter.

If you are an MBA student facing a unique kind of business school proposal, you can rest assured that your gap identification and methodology will meet the business school’s expectations right from the beginning.

FAQs

How long should a dissertation proposal be?

Length varies by institution and level. Master’s proposals typically range from 1,000 to 3,000 words. Always follow your department’s specific guidelines.

Can I change my proposal after it has been approved?

Minor adjustments are generally permitted as research evolves. Significant changes usually require supervisor approval or a formal amendment.

What is the most common reason proposals are rejected?

A research question that is too broad, a literature review that summarises rather than synthesises, or a methodology that is named but not justified.


INTERESTING POSTS

What a VPN Can and Cannot Protect You From Online

0
What a VPN Can and Cannot Protect You From Online

In this post, I will show you what a VPN can and cannot protect you from online.

Online privacy and cybersecurity have become major concerns for internet users worldwide. From browsing websites and using public Wi-Fi to shopping online and accessing financial services, people constantly transmit data across networks. Cybercriminals, malicious actors, and other security threats can exploit poorly protected connections, making it increasingly important to understand the tools available to improve online security.

One of the most popular privacy tools is a virtual private network (VPN). Websites such as Flippendo provide information about VPNs and related online privacy technologies, helping internet users better understand the tools available to protect their online activities. However, while a VPN can significantly improve privacy and connection security, it cannot protect users from every online threat.

What Does a VPN Actually Do?

A VPN creates an encrypted connection between your device and a remote VPN server. Instead of connecting directly to websites and online services, your internet traffic is routed through the VPN server before reaching its destination.

This process provides two major benefits. First, encryption can make it more difficult for unauthorized parties on the network to inspect your internet traffic. Second, websites and online services generally see the VPN server’s IP address rather than your original public IP address.

These capabilities make VPNs useful privacy and security tools, particularly when combined with other cybersecurity practices.

What Can a VPN Protect You From?

What Can a VPN Protect You From?

1. Exposure of Your Public IP Address

When you browse the internet without a VPN, websites and online services can typically see your public IP address. Although an IP address does not reveal every detail about you, it can reveal your approximate geographical location and internet service provider.

A VPN masks your original public IP address by routing your connection through another server.

2. Some Risks Associated With Unsecured Networks

Public Wi-Fi networks in airports, hotels, restaurants, and other public locations can introduce security and privacy risks.

A VPN encrypts traffic between your device and the VPN server, adding an important layer of protection when using networks you do not fully trust.

However, VPN users should still follow basic cybersecurity practices when connecting to public Wi-Fi.

3. Certain Forms of Network Monitoring

Depending on the technologies and protocols involved, network operators may be able to observe information about internet activity.

Using a VPN encrypts the connection between your device and the VPN provider, making the contents of that traffic more difficult for local network observers to inspect.

It is worth remembering, however, that using a VPN shifts some of your trust. Choosing a reputable VPN provider with transparent privacy policies and strong security practices remains important.

What Can a VPN Not Protect You From?

What Can a VPN Not Protect You From?

Understanding the limitations of VPN technology is just as important as understanding its benefits.

1. Phishing Attacks

A VPN cannot prevent you from clicking a malicious link, entering your password into a fraudulent website, or responding to a deceptive email.

Cybercriminals frequently use social engineering techniques to manipulate users into voluntarily providing sensitive information.

Protection against phishing requires awareness, careful verification of websites and messages, and appropriate security tools.

2. Malware and Ransomware

VPN software is not a replacement for antivirus or endpoint security solutions.

If you download a malicious attachment, install infected software, or execute ransomware, a VPN may do little to prevent the device from becoming compromised.

Keeping operating systems and applications up to date and using appropriate security software remain essential components of a comprehensive cybersecurity strategy.

3. Weak or Stolen Passwords

A VPN cannot secure an account protected by a weak password.

If attackers obtain your login credentials through a data breach, phishing campaign, or password reuse attack, they may still be able to access your accounts.

Internet users should create strong, unique passwords and enable multi-factor authentication whenever possible.

4. Online Tracking Through Accounts and Cookies

VPNs can hide your original public IP address, but websites have other methods of identifying and tracking users.

Cookies, browser fingerprinting, advertising technologies, and logged-in accounts can still be used to associate online activities with a particular user or device.

For better privacy, users should combine VPN technology with privacy-conscious browser settings and careful management of online accounts and permissions.

5. Information You Voluntarily Share

No VPN can protect information that users intentionally publish online.

Posting personal details, sensitive photographs, travel plans, contact information, or other private data on social media can create privacy and security risks regardless of whether a VPN is active.

A VPN Should Be Part of a Larger Cybersecurity Strategy

A VPN Should Be Part of a Larger Cybersecurity Strategy

The most effective approach to online protection is to use multiple layers of security.

A VPN can provide connection encryption and IP address masking, but users should combine these capabilities with strong passwords, multi-factor authentication, updated software, antivirus protection, secure browser settings, regular backups, and awareness of phishing and social engineering attacks.

This layered approach is often more effective because cyber threats can target different parts of a user’s digital life.

Final Thoughts

VPNs can be valuable tools for improving online privacy and protecting internet connections. They can help mask public IP addresses, encrypt traffic between devices and VPN servers, and provide additional protection when using unfamiliar networks.

However, VPNs are not complete cybersecurity solutions.

They cannot automatically prevent phishing attacks, malware infections, password theft, unsafe downloads, invasive browser tracking, or the consequences of sharing sensitive information online.

The key is to understand what VPN technology is designed to do and use it alongside other cybersecurity tools and responsible online habits.

By taking a layered approach to digital security, internet users can build stronger defenses against online threats while maintaining greater control over their privacy.


INTERESTING POSTS

How An SPF Record Can Instantly Improve Your Email Deliverability

0
How An SPF Record Can Instantly Improve Your Email Deliverability

In this post, I will show you how an SPF Record can instantly improve your email deliverability.

The Sender Policy Framework (SPF) is an essential email authentication system aimed at preventing email spoofing and enhancing the chances of email delivery. Essentially, an SPF record is a specific type of TXT record within the Domain Name System (DNS) that specifies which mail servers are permitted to send emails on behalf of a particular domain.

When an email server processes an incoming email, the receiving Mail Transfer Agent (MTA) looks up the SPF record associated with the domain found in the envelope from the header. By comparing the connecting server’s IP address to the list of authorized senders in the SPF record, the MTA can assess whether the email is genuine or potentially a spoof, thereby significantly lowering the likelihood of fraudulent emails landing in users’ inboxes. 

The effectiveness of email authentication relies on SPF working together with DKIM (DomainKeys Identified Mail) and DMARC (Domain-based Message Authentication, Reporting, and Conformance). Leading business email services, including Google Workspace, Microsoft 365, Zoho Mail, and Amazon SES, highly recommend proper SPF setup to bolster the credibility of outgoing emails.

Additionally, spam filtering solutions like Mimecast, Barracuda Networks, and Proofpoint utilize SPF as a key indicator in their anti-spam and anti-phishing measures.

How SPF Helps Improve Email Deliverability Instantly

SPF provides organizations and brands with quick advantages by establishing a clear sender policy for their domains. Once the SPF record is published, it offers several key benefits for email deliverability:

  • Prevents Unauthorized Senders: Only designated IP addresses and email servers are allowed to send emails “on behalf of” your domain. This robust validation process protects against email spoofing by malicious entities.
  • Lowers Spam and Phishing Threats: Major email service providers like Gmail, Outlook, and Yahoo Mail, as well as security services such as Cisco Talos, Spamhaus, and SpamExperts, place significant emphasis on SPF verification within their spam-filtering systems. A valid SPF record enhances the chances of your emails reaching recipients’ inboxes rather than being marked as spam.
  • Supports DMARC Compliance: For compliance with DMARC policies, SPF authentication connects the envelope from domain to your SPF policy. When both SPF and DKIM successfully align, your emails are considered highly trustworthy.
  • Immediate Results: The benefits of a correctly set up SPF record are almost instantaneous; most receiving mail servers and Mail Transfer Agents will check the SPF policy for every incoming message. Thus, SPF boosts email deliverability as soon as DNS propagation is finished.

Common SPF Record Syntax, Mechanisms, and Examples

Common SPF Record Syntax, Mechanisms, and Examples

Understanding SPF Syntax

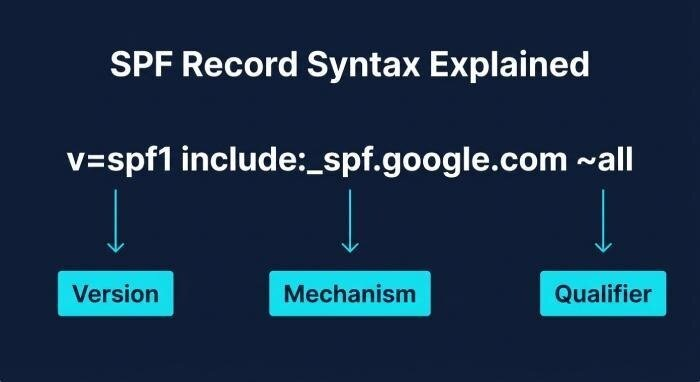
SPF records follow a specific syntax as outlined in RFC 7208. Each record begins with the version of SPF and includes various mechanisms and qualifiers that collectively specify which IP addresses and hosts are permitted.

Key SPF Mechanisms

  • ip4 & ip6: Define permitted IPv4 or IPv6 addresses and ranges. 

  Example: `ip4:192.0.2.0/24`

  • a & mx: Allow any IP addresses returned from A/AAAA or MX records associated with the domain. 

  Example: `mx`

  • include: Permits the SPF policy of another domain, which is particularly handy for known senders like SendGrid, Amazon SES, or Mailgun. 

  Example: `include:sendgrid.net`

  • ptr: (Seldom recommended) Allows mail from IPs that have reverse DNS PTR records matching your domain.
  • all: Matches every IP address, usually placed at the end of the record with its respective qualifier.

SPF Qualifiers

  • + (Pass): Explicitly permits (implied when absent).
  • – (Fail): Clearly denies.
  • ~ (Softfail): Identifies but does not reject.
  • ? (Neutral): Indicates no specific policy or preference.

SPF Record Examples

Basic SPF Record Example

  • v=spf1 ip4:198.51.100.23 include:mailgun.org -all
  • Only the designated IP address and Mailgun’s servers are authorized to send emails for this domain.

Complex SPF Record Example

  • v=spf1 ip4:35.190.247.0/24 ip4:64.233.160.0/19 mx include:spf.protection.outlook.com include:_spf.google.com -all
  • This configuration permits email from specific IP addresses, as well as from Google Workspace and Microsoft 365 (Outlook) servers.

How SPF Mechanisms and Qualifiers Work Together

When a server’s IP address aligns with an authorized sender listed in the SPF record, the outcome is an SPF pass. If it doesn’t match, the result — whether it’s an SPF fail, softfail, or neutral — will depend on the specific mechanism and qualifier used. By configuring this accurately, genuine email servers and SMTP relays are more likely to achieve a pass, which enhances email deliverability.

How to Create, Publish, and Test an SPF Record

Planning and Creating an SPF Policy

Prior to launching, conduct a comprehensive inventory of all email sources associated with your domain, including Google Workspace, Microsoft 365, Amazon SES, Mailchimp, newsletters (such as Postmark, Sendinblue, SparkPost), and any bespoke email servers or on-site SMTP relays. It’s essential that each service provides SPF includes or IP addresses to be used as mechanisms.

To minimize syntax mistakes and guarantee policy correctness, many administrators turn to SPF record generators provided by platforms like AutoSPF, Netcore, Trustifi, Fastmail, Namecheap, or Dmarcian.

Publishing SPF in the Domain Name System

  1. Access your DNS hosting provider, which could be GoDaddy, Cloudflare, Bluehost, or Namecheap.
  1. Create or modify a TXT record at either the domain root or a subdomain:

Set the host/name to `@` or the relevant subdomain.

Input your SPF record string into the value/data field.

  1. Save the changes and wait for DNS propagation (usually takes less than an hour). By publishing this as a TXT record in the Domain Name System, you enable MX records and Mail Transfer Agents globally to access and implement your SPF policy.

Testing and Validating Your SPF Record

SPF Validation Tools

Once you’ve made your SPF records public, it’s advisable to utilize an SPF testing tool for verification. Some suggested tools are MxToolbox, EasyDMARC, Dmarcian, and Cisco Talos.

  • MXToolbox: Detects syntax mistakes in SPF, evaluates mechanisms, counts lookups, examines policies, and more.
  • EasyDMARC: Confirms the alignment of DMARC, DKIM, and SPF.

Conducting routine checks on your SPF records guarantees that your approved senders consistently pass validation, helping to maintain the best possible email deliverability.

READ ALSO: Use An SPF Checker To Diagnose DNS And Mail Server Problems

SPF Record Update and Migration

Whenever you incorporate new authorized sending services — such as transitioning to Zoho Mail or integrating with Mailchimp or Barracuda Networks — ensure that you promptly revise your SPF record. During the process of migrating email services (for example, switching to Google Workspace or Outlook), it’s essential to check your SPF alongside related DKIM and DMARC configurations, ensuring that domain alignment remains intact for optimal deliverability.

SPF Best Practices and Mistakes to Avoid

SPF Best Practices and Mistakes to Avoid

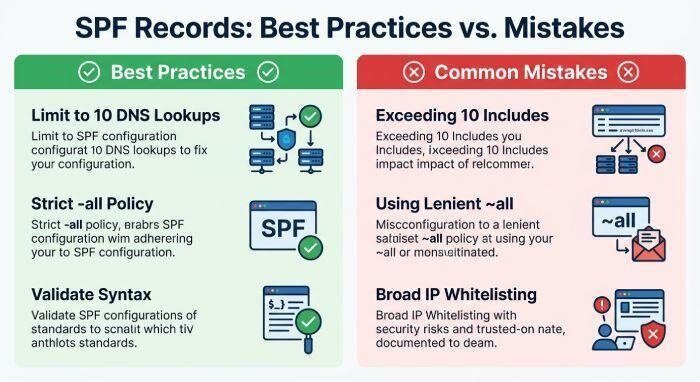
Follow Key SPF Policy Best Practices

  • Reduce Includes and Lookups: Be mindful that the SPF lookup threshold is capped at 10 DNS queries per policy. Adding too many includes, particularly for services like SendGrid or Atmail, may lead to SPF failures due to exceeding this limit. Consider using SPF flattening when required.
  • Authorize Only Essential Senders: Avoid unnecessarily broadening your sender policy by whitelisting unneeded IP ranges or entire networks of providers.
  • Maintain Clear Syntax: Steer clear of frequent SPF syntax mistakes. Utilize SPF record validators to identify missing or incorrectly placed qualifiers and broken includes.
  • Monitor Record Size: Records that are too lengthy can surpass DNS limits; streamline or flatten them as needed.
  • Test Across All Mailflows: Ensure that every outgoing mail scenario — be it transactional, newsletters, or system alerts — is validated with SPF testing tools to confirm successful SPF passing and alignment.

Avoid Common Mistakes

  • Inadequate Include Chains: Failing to monitor includes may lead to unnecessary lookups or create circular dependencies. It’s essential to assess how these additions affect the SPF lookup limit.
  • Neglecting Important Providers: Omitting the IP address of a genuine mail server (or the correct MX record) can lead to valid emails encountering SPF failures or softfails, negatively impacting deliverability.
  • Relying Solely on ‘Neutral’ or ‘Softfail’: An overly lenient SPF policy lacks effectiveness. For most domains, it’s advisable to use `-all` (fail) as the conclusive qualifier unless there is a strong operational justification to do otherwise.

Stay Up to Date

Establish a regular timeline for updating your SPF records, particularly after introducing new services, modifying DNS hosting, or during extensive SPF transitions. Ensure that your DKIM and DMARC settings are consistently aligned for optimal email authentication and domain security.

By effectively managing your SPF records, you enhance your domain’s defenses against spoofing, safeguard legitimate sending sources, and achieve maximum email deliverability both now and moving forward.


INTERESTING POSTS

DMARC Generator Guide: Create, Check, And Publish DMARC Records

0
DMARC Generator Guide: Create, Check, And Publish DMARC Records

In this post, I will give you the DMARC Generator Guide and show you how to create, check, and publish DMARC records.

Email security is no longer optional in today’s threat landscape, making DMARC an essential component of domain protection. This guide explains how to create, check, validate, and publish DMARC records using a DMARC generator.

Whether you’re new to email authentication or looking to strengthen existing protections, you’ll learn how DMARC policies, reporting options, alignment settings, and enforcement levels work together to prevent phishing, spoofing, and unauthorized email use while improving deliverability and domain reputation.

What a DMARC Generator Is and Why It Matters

A DMARC generator tool is an essential solution designed to help organizations quickly and accurately create DMARC records for their domains. As email threats escalate, particularly phishing, Business Email Compromise (BEC), and domain spoofing, implementing a robust DMARC record is crucial for any business prioritizing email authentication and email security. By using a DMARC generator tool, organizations can simplify record creation, reduce configuration errors, and strengthen protection against email-based attacks.

By leveraging a DMARC record generator, security professionals and domain administrators can generate DMARC records with correct syntax and tailored policies—without requiring extensive technical knowledge. Solutions from providers like EasyDMARC, PowerDMARC, and MXToolbox simplify this process, making strong email authentication far more accessible for organizations ranging from Fortune 100 companies to mid-market enterprises.

The DMARC generator walks users through all the necessary tags and options needed to create an error-free DMARC record in the appropriate TXT record format for your DNS zone. This ensures not only basic compliance, but also safeguards your domain against impersonation attacks, ransom threats, and unwanted messages, which can severely damage business reputation and deliverability.

Key DMARC Record Tags Explained: Policy, Alignment, Reports, and Enforcement

DMARC records consist of several policy tags, each representing specific instructions and protocols for mail handling and reporting. Understanding each of these tags is vital when you generate a DMARC record—whether with a generator or manually.

Key DMARC Record Tags Explained: Policy, Alignment, Reports, and Enforcement

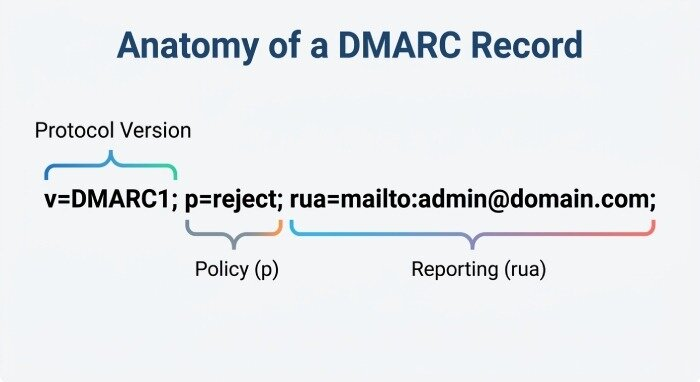
Policy Type (p=): none, quarantine, reject

The policy type is fundamental in any DMARC policy. It tells ISPs and mail receivers what to do with emails that fail DMARC authentication checks:

  • none: Monitoring mode. Email messages failing DMARC are still delivered, but you receive reports to your aggregate address. Ideal for initial implementation and analysis.
  • quarantine: Suspicious emails are routed to the recipient’s spam or junk folder.
  • reject: The strongest setting, instructing receivers to block delivery of messages failing DMARC validation.

Subdomain Policy (sp=)

The subdomain policy specifies what happens to emails sent from subdomains of your primary domain:

  • If omitted, the parent domain’s policy applies.
  • Set as none, quarantine, or reject for tailored subdomain handling.

Alignment: SPF and DKIM (aspf=, adkim=)

Alignment tags dictate how strictly the system matches the authorized SPF domain and DKIM signature to the Header From domain (Parent Header From domain):

  • SPF alignment (aspf=) and DKIM alignment (adkim=) can be set as relaxed or strict.
  • relaxed: Allows minor domain mismatches (e.g., sub.example.com and example.com).
  • strict: Requires an exact domain match.

Reporting Options: Aggregate and Failure (RUA, RUF)

Reporting allows you to monitor protocol outcome and fine-tune your DMARC settings:

  • Aggregate report (RUA address / rua=): Receives DMARC XML summary reports from ISPs for statistical insights.
  • Failure report (RUF address / ruf=): Receives forensic or instant DMARC failure reports (forensic report).
  • Reporting interval (ri=): Determines how often aggregate reports are sent, generally in seconds (e.g., 86400 for daily).

Other Tags and Parameters

  • Policy percentage (pct=): Applies the policy type to a specified percentage of your mail stream for gradual implementation.
  • Record type: Always set as a TXT record in your DNS.
  • Policy tags: Each tag (e.g., p, sp, adkim, aspf, rua, ruf, pct) contributes to clear, enforceable instructions.

DMARC Record Format

A valid DMARC record example looks like this:

v=DMARC1; p=quarantine; rua=mailto:dmarc-reports@yourdomain.com; ruf=mailto:forensics@yourdomain.com; adkim=strict; aspf=relaxed; sp=none; pct=100; ri=86400

READ ALSO: Online DMARC Record Generator For Fast Email Security Setup

How to Create a DMARC Record with a DMARC Generator

Deploying a DMARC record begins with properly crafting the record itself. Using a DMARC generator or DMARC record generator streamlines this process, guiding you through each mandatory and optional field.

Steps to Generate DMARC Record

1. Select Your Policy (none, quarantine, reject)

Start by identifying your intended DMARC policy type. New users often begin with none for monitoring, moving gradually to quarantine or reject as authentication improves.

2. Configure Alignment Options

Choose between relaxed and strict modes for SPF alignment and DKIM alignment. This directly affects the stringency of your authentication checks.

3. Input Reporting Details

Enter your RUA address and RUF address for receiving aggregate and forensic DMARC reports. These addresses must be valid mailboxes, ideally separate from main business operations for security.

4. Set Subdomain Policy and Policy Percent

Specify the subdomain policy if you want a different enforcement level for your subdomains. Adjust policy percentage as needed for phased rollouts.

5. Review Generated Syntax

A robust DMARC generator will generate DMARC record syntax and present a valid DMARC ready for DNS entry. Providers such as EasyDMARC, MXToolbox, and PowerDMARC offer intuitive interfaces and instant previews of your configuration.

6. Manual DMARC Record Option

Advanced users may wish to create a manual DMARC record, by following correct tag placement and formatting as described in RFC 7489. However, even experts benefit from generators to avoid common syntax errors.

How to Check, Validate, and Troubleshoot Your DMARC Record

After you generate DMARC record content, validation and troubleshooting are critical.

Using DMARC Checker Tools

Upload your DMARC record to a DMARC checker or record checker like EasyDMARC, MXToolbox, or SuperTool. These tools analyze for:

  • Syntax and formatting problems
  • Correct inclusion of essential policy tags (p, rua, etc.)
  • Valid RUA/RUF reporting options
  • Compatibility with your DNS zone and provider

Validating in Your DNS

Ensure the DMARC record is published as a TXT record on the _dmarc hostname (Host/Name) in your DNS:

  • Example: _dmarc.yourdomain.com as the Name/Host.
  • Confirm correct record format and ensure your DNS provider (such as GoDaddy) propagates updates quickly.

Troubleshooting Common Issues

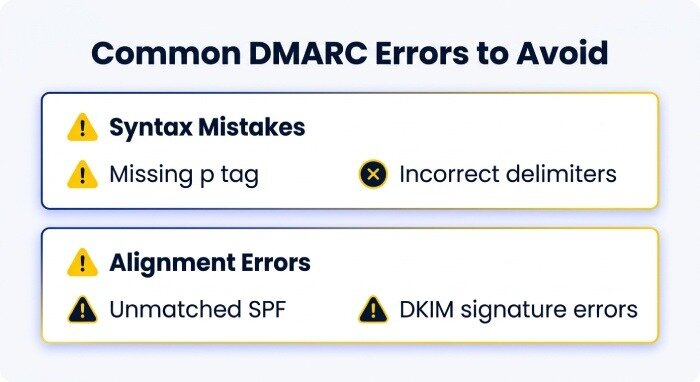
Syntax and Policy Mistakes

  • Missing mandatory tags (such as p)
  • Incorrect delimiter usage (all tags must end with semicolons)
  • Malformed reporting addresses (RUA/RUF)

Authentication Alignment Errors

  • Unmatched SPF identifier or DKIM signature
  • Incorrect subdomain policy references

Achieving an Error-free DMARC Record

Achieving an Error-free DMARC Record

Iterate on your record format using both DMARC record generators and manual inspections. Seek out tools and certifications, referencing community reviews from G2 Crowd, Expert Insights, SourceForge, and BetterTracker for authoritative guidance.

How to Publish Your DMARC Record and Move Toward Enforcement

Proper publication of your DMARC policy is essential for full protection and improved deliverability.

Publishing in the DNS Zone

  • Access your DNS provider’s management portal (e.g., GoDaddy).
  • Add a new TXT record at the _dmarc subdomain of your chosen domain.
  • Paste the content generated by your DMARC record generator as the Value/Data field.
  • Allow for DNS propagation, which can take from a few minutes to 48 hours depending on your provider and DNS infrastructure.

Monitoring and Incremental Enforcement

Upon initial publication, set your policy type to none and review aggregate and failure DMARC reports. Analyze those reports using solutions like Delivery Center to track authentication checks, protocol outcomes, and sources of email traffic.

Gradually migrate from monitoring (none) to quarantine and then reject as your legitimate senders pass SPF and DKIM checks. Carefully review feedback on deliverability to ensure no valid mail is blocked during each phase.

Maintaining and Updating Your DMARC Policy

Regularly review your DMARC records as your email services, subdomains, or partners change. Adjust reporting options or subdomain policy to reflect operational updates, and always verify changes with a DMARC checker before applying them in production.

Taking these steps will ensure a valid, error-free DMARC implementation, maximizing email security, phishing protection, and corporate reputation.


INTERESTING POSTS

Before You Automate Your RFP Process, Read This

0
Before You Automate Your RFP Process, Read This

In this post, I will show you what to do before you automate your RFP process.

The pitch for RFP automation is compelling: respond faster, reuse content intelligently, reduce the burden on subject matter experts, and free your best people to focus on strategy rather than formatting. All of that is true – when automation is applied to a process that’s ready for it.

The part that doesn’t make it into vendor demos: automation applied to a broken process doesn’t fix the process. It accelerates it. An accelerated broken process produces broken outputs at scale, faster than you could manage when everything was manual.

This is not an argument against automating your RFP workflow. It’s an argument for understanding what automation can and can’t do – so that when you implement it, it actually works.

What Automation Is Really Doing

Most teams think of RFP automation as a speed tool. Get answers out faster, fill more fields, hit more deadlines. That framing isn’t wrong, but it’s incomplete.

At its core, RFP automation is a knowledge management and retrieval system. The foundational capability is this: given a question in an RFP, surface the most relevant, accurate, and current answer from your content library – without requiring someone to search manually, chase down a subject matter expert, or reinvent the wheel for the fifteenth time.

Everything else – AI-assisted drafting, workflow routing, automated assignments, compliance tracking – is built on top of that foundation. And that foundation is only as strong as the quality of what’s in your content library.

This is why the most common failure mode in RFP automation isn’t the technology. It’s the content. Teams implement a sophisticated automation platform, point it at a library full of outdated answers, inconsistent messaging, and legacy case studies, and wonder why the AI-generated drafts need to be rewritten from scratch before they’re usable. The automation isn’t failing. It’s faithfully surfacing bad content at speed.

The Three Layers of RFP Automation

Understanding what you’re actually automating helps clarify where to invest and in what sequence.

Layer 1: Content Retrieval and Suggestion

This is the baseline function of any serious RFP automation tool. When a question comes in – “Describe your data security protocols” or “What is your uptime SLA?” – the system searches your content library and surfaces the most relevant existing answer.

Done well, this eliminates the most time-consuming part of RFP response: the search. Instead of a proposal manager digging through shared drives, past proposals, and Slack threads to find the right answer, the system does that retrieval automatically. The human reviews and approves, rather than hunts and assembles.

The quality gate here is content maintenance. If the content library isn’t actively maintained – with clear owners, regular review cycles, and a process for adding new wins, certifications, and product updates – content retrieval becomes content retrieval of stale material. Fast, but wrong.

Layer 2: AI-Assisted Drafting

The next layer uses AI to do more than retrieve – it synthesises. Given a question and relevant source material, it generates a draft response that can be reviewed, edited, and approved rather than written from scratch.

This is where most of the current excitement in RFP automation lives, and for good reason: the productivity gains are real. A proposal manager who previously spent three hours drafting responses to a security questionnaire can now spend 45 minutes reviewing and refining AI-generated drafts. That’s not a marginal improvement – it’s a structural change in how response capacity works.

The critical caveat is accuracy. AI-assisted drafting is confident by design. It produces fluent, well-structured prose regardless of whether the underlying facts are correct. This means the review step is not optional – it’s where the human adds the most value, catching inaccuracies, outdated claims, and mismatched context before they go out the door.

Teams that treat AI-generated drafts as final outputs rather than starting points are taking on significant risk, particularly in regulated industries where incorrect compliance claims have real consequences.

Layer 3: Workflow and Process Automation

The third layer is about orchestrating the human side of the process: routing questions to the right subject matter expert, tracking completion status across sections, managing approval gates, sending deadline reminders, and maintaining an audit trail of who reviewed and approved what.

This is the layer most teams underestimate. Content retrieval gets the attention. Workflow automation is what makes the process actually function as a system rather than a series of ad hoc decisions.

Good workflow automation means that when an RFP comes in, the intake, triage, assignment, and kickoff sequence happens in a defined, repeatable way – not however the proposal manager decides to handle it this week. It means that subject matter expert assignments are tracked, deadlines are visible to everyone, and bottlenecks surface automatically rather than being discovered the day before submission.

What Breaks When You Automate Too Early

Teams that jump to automation before their process fundamentals are solid tend to encounter the same set of problems.

Garbage in, garbage out – at scale: This is the content quality problem described above. Automation amplifies whatever is in your library. If your library is good, automation makes your response process dramatically better. If your library is mixed quality, automation will reliably surface the wrong answers alongside the right ones, and the review burden actually increases because reviewers can’t trust the outputs.

False confidence in AI-generated content: The fluency of AI-generated prose creates a subtle risk: it looks authoritative even when it’s wrong. Teams under deadline pressure will approve drafts they’ve only skimmed, particularly if the content sounds plausible. In RFP responses, where accuracy on security, compliance, and integration claims can make or break a deal – or create post-sale problems – this is a serious exposure.

Automation of a bad workflow: If your current RFP response workflow has unclear ownership, late reviews, and a go/no-go process that defaults to yes, automating it will make those problems harder to see and harder to fix. The chaos becomes invisible because the tools are handling it – until something goes wrong and you realise the tools were managing around structural problems rather than resolving them.

Expert disengagement: One of the promises of RFP automation is to reduce the burden on subject matter experts. This is real – but there’s a failure mode where experts disengage from the process entirely because “the AI handles it now.” The result is content that becomes progressively more stale and less accurate, with no human check on quality because the experts stopped looking.

The Readiness Assessment Most Teams Skip

Before investing in an automation platform, a structured readiness assessment is worth doing. It doesn’t have to be elaborate – but it needs to be honest.

Content audit: What’s actually in your content library? When was it last reviewed? Who owns it? How much of it is genuinely current and accurate? If you can’t answer these questions, the first investment is not automation – it’s content governance.

Process mapping: Can you describe your current RFP response process in enough detail that a new hire could follow it? If the answer is “it depends on the RFP,” that’s a sign the process isn’t defined enough to automate effectively. Automation formalises what exists – if what exists is ad hoc, you’ll formalise the ad hoc.

Volume and velocity assessment: Automation delivers the most value above a certain volume threshold. If you’re responding to five RFPs a month, the overhead of maintaining an automation platform may exceed the time saved. If you’re handling fifty, the math changes completely. Be honest about your actual volume and trajectory.

Team capability: Automation tools require ongoing administration – content updates, library curation, workflow configuration, and performance monitoring. Who will own this? Is that person’s capacity accounted for in the business case?

For teams working through this assessment, the practical framework laid out in this resource on rfp automation covers not just what automation tools do, but how to evaluate whether your organisation is positioned to get value from them – including the readiness questions most evaluations skip.

When Automation Actually Delivers

With the caveats on the table, it’s worth being direct: when the conditions are right, RFP automation delivers meaningful, compounding value.

Teams with well-maintained content libraries see turnaround times cut by 40–60% on standard RFPs. Subject matter experts report spending significantly less time on repetitive questions. Proposal managers shift from assembly work to strategic editing. Consistency improves – responses no longer vary dramatically based on who happens to be available this week.

The compounding effect is the part that doesn’t show up in initial ROI calculations. Every RFP cycle generates data: which content was used, which answers required significant editing, and which sections took the longest to complete. Teams that use this data systematically get better with each cycle. Their libraries improve. Their automation gets more accurate. Their win rates tick up not because they wrote a better proposal this week, but because their system is better than it was six months ago.

That’s the real promise of rfp automation – not faster proposals, but a response capability that learns and improves over time, compounding the advantage of every investment in process and content quality.

The Sequencing That Works

If you’re building toward automation, the sequence matters:

First: Fix content governance. Define owners for each content area, establish review cadences, and do an honest audit of what’s current and what isn’t. This work pays off with or without automation.

Second: Document and stabilise your process. Map the current state, identify where it consistently breaks down, and fix the structural problems before you codify them in software.

Third: Automate incrementally. Start with content retrieval and suggestion. Let the team build confidence in the tool and develop the habits – review discipline, content update cycles, expert feedback loops – that make automation work. Then add AI-assisted drafting. Then automate the workflow layer.

Fourth: Close the feedback loop. Build in post-submission reviews that capture what worked and what didn’t, and use that data to improve content quality continuously.

This sequence is slower than buying a platform and going live next month. It’s also significantly more likely to produce the outcomes you actually want – a response process that’s faster, more consistent, and genuinely better over time.

The goal isn’t automation. The goal is winning more of the right deals, consistently, with less organisational pain. Automation is one of the most powerful tools available for getting there. But it’s a tool, not a strategy – and the difference between those two things is where most implementations succeed or fail.


INTERESTING POSTS